Transforming 19th-Century Legal Archives into a Searchable Knowledge Base Using AI Pipeline Techniques
Dor Peleg4 min read
Key facts
RILLOO built an AI pipeline that turns 19th-century French legal newspaper images into a semantically searchable database, using Gemini 2.5 Pro for OCR correction and classification and Google Embeddings with FAISS for search. Administrators query and manage the archive through an MCP server.
- Industry
- Legal
- Challenge
- 19th-century French legal newspapers stored as images had degraded text, archaic spelling and mixed content, so standard OCR produced unusable output.
- Solution
- An automated pipeline that ingests archive images, uses Gemini 2.5 Pro for OCR with contextual correction and classification, and indexes Google Embeddings in FAISS, queryable through an MCP server.
- Results
- Researchers and legal historians can search the archive with semantic precision
- Skip logic and cost tracking keep processing costs under control
- Supports continuous ingestion as the archive grows
- Technologies
- Gemini 2.5 ProRAGGoogle EmbeddingsFAISSModel Context Protocol (MCP)
Digitizing 19th-century French legal archives presents a unique set of challenges. The original materials are often fragile, the text is degraded, and the spelling reflects an era long past. Traditional Optical Character Recognition (OCR) tools struggle to accurately capture this content, leaving vast amounts of historical data inaccessible. This case study explores how RILLOO built a sophisticated AI pipeline to convert these chaotic archives into a fully searchable vector database, enabling semantic search and interactive exploration.
From faded newspaper pages to a searchable legal knowledge base
The Challenge of Chaotic Input Data
The project began with a massive collection of 19th-century French newspapers, primarily legal documents, stored as HEIC/HEIF images. These image formats are high-efficiency but not widely supported in traditional OCR workflows. The archives presented several obstacles:
- Image format complexity: HEIC/HEIF images required custom ingestion and conversion pipelines to prepare them for processing.
- Degraded text quality: Age, wear, and scanning artifacts caused blurring, stains, and missing characters.
- Archaic French spelling: The language used in the 1800s differs significantly from modern French, with obsolete words and inconsistent orthography.
- Mixed content types: Pages contained legal notices, financial reports, and general news, often interwoven without clear separation.
Standard OCR engines failed to deliver reliable results due to these factors. They produced noisy text with many errors, making downstream search and analysis ineffective.
Building the “Smart” Ingestion Pipeline
To handle continuous ingestion of new data and scale efficiently, we designed an automated pipeline with several key features:
Automated Monitoring
The system continuously watches designated iCloud folders where new HEIC/HEIF images arrive. This real-time monitoring triggers ingestion workflows without manual intervention, ensuring the archive grows dynamically.
Smart Skip Logic
Duplicate detection is critical when dealing with large historical collections that may contain overlapping or repeated editions. Our pipeline implements Smart Skip Logic to identify and skip duplicate or near-duplicate images. This reduces unnecessary processing and storage costs.
Image Pre-Processing
Before OCR, images undergo several enhancement steps:
- De-noising to reduce scanning artifacts.
- Contrast adjustment to improve text visibility.
- Deskewing and cropping to align text blocks properly.
- Format conversion from HEIC/HEIF to PNG or TIFF for compatibility.
These steps improve OCR accuracy and speed, especially at scale.
The AI Core: Gemini 2.5 and RAG Pipeline
At the heart of the system lies the AI core, combining Google Gemini 2.5 Pro with a Retrieval-Augmented Generation (RAG) pipeline to extract, correct, and classify text.
OCR and Contextual Correction
Gemini 2.5 Pro goes beyond simple character recognition. It reads the text and applies contextual correction tailored to 19th-century French. This involves:
- Recognizing archaic spellings and mapping them to modern equivalents without losing historical authenticity.
- Correcting common OCR errors by leveraging language models trained on historical corpora.
- Preserving legal terminology and formatting critical for accurate interpretation.
This approach significantly improves text quality compared to off-the-shelf OCR.
Segmentation by Content Type
The AI classifies sections into Legal, Financial, and News categories based on header detection and layout cues. This segmentation allows users to filter search results by document type, improving relevance and user experience.
Search Architecture Using Google Embeddings and FAISS
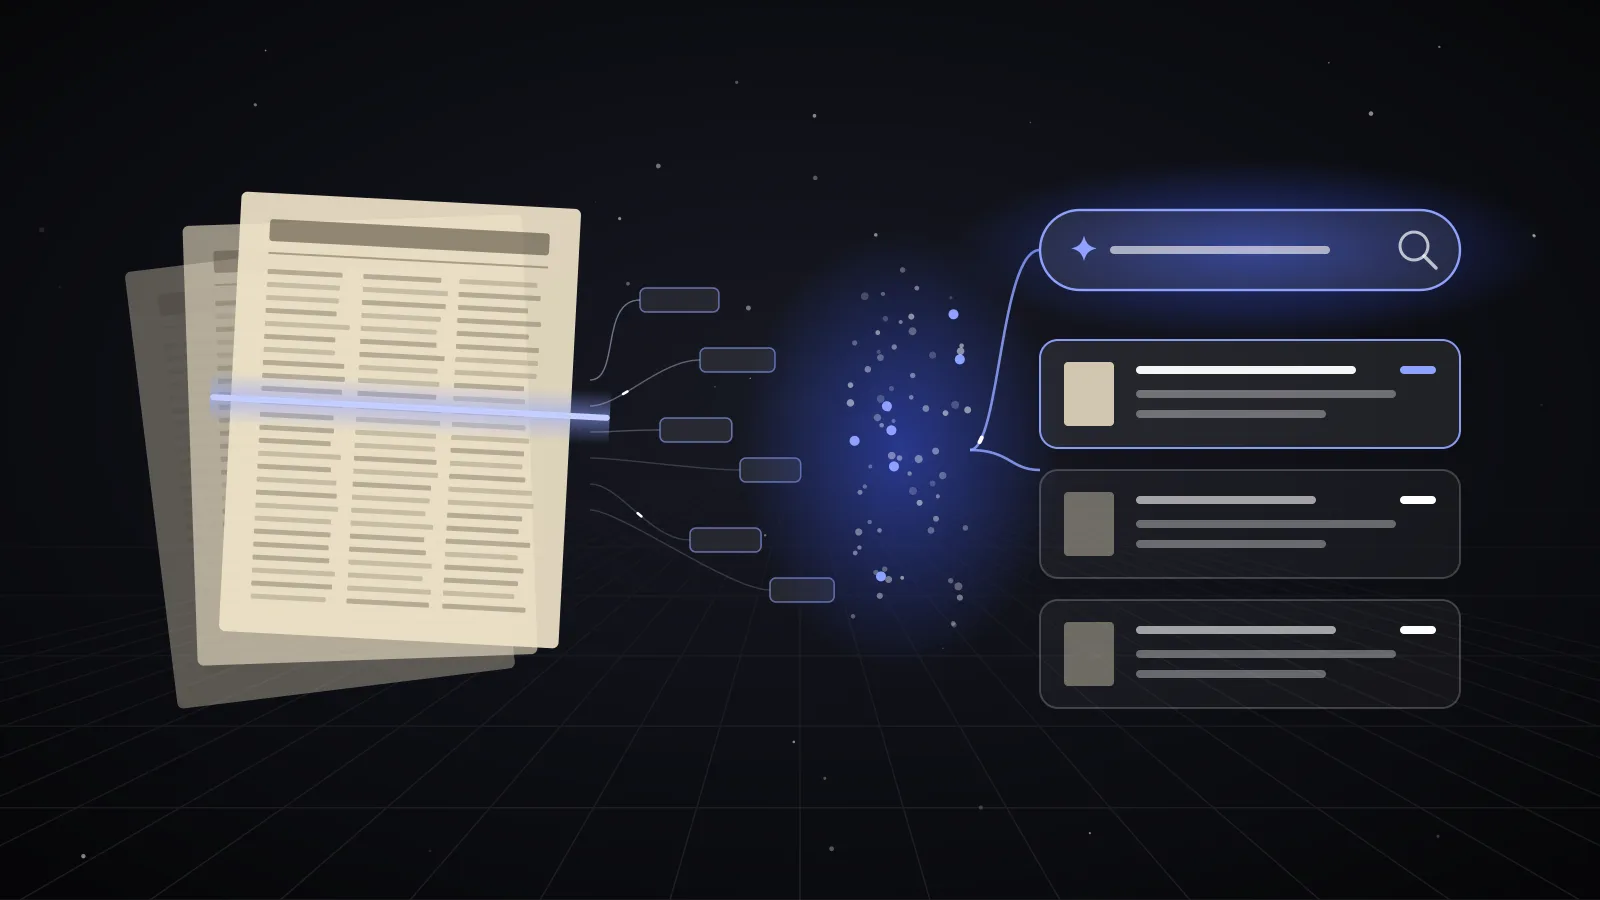
To enable semantic search, the cleaned and segmented text is embedded into vector space using Google Embeddings. This representation captures the meaning of text beyond keywords.
We use FAISS, Facebook’s efficient similarity search library, to index these vectors. This setup allows:
- Fast retrieval of documents based on conceptual similarity.
- Queries that find related legal concepts even if exact keywords differ.
- Scalable search across millions of text segments.
The combination of embeddings and FAISS transforms the archive into a living knowledge base where users can explore ideas, not just words.
Semantic search interface showing historical legal documents and vector search results
Innovation with Model Context Protocol and IDE Integration
A standout feature of this project is the integration of the Model Context Protocol (MCP) server with the Cursor IDE, creating a seamless workflow for developers and administrators.
Model Context Protocol Server
MCP acts as a bridge between the AI models and the document corpus. It manages:
- Query routing to appropriate models.
- Contextual awareness of document metadata and user queries.
- Real-time updates as new data arrives.
Cursor IDE Integration
Through MCP, users can query the archive, view documents, and run administrative tools directly within Cursor IDE. This integration offers:
- Immediate feedback on search queries.
- Tools to inspect and correct OCR outputs.
- Model-specific cost tracking to monitor resource usage.
This workflow reduces friction in managing large unstructured datasets and accelerates development cycles.
Business Impact and Outcomes
The project turned previously inaccessible “dead data” into a live, interactive knowledge base. Key outcomes include:
- Improved access: Researchers and legal historians can now search and explore archives with semantic precision.
- Cost efficiency: Smart Skip Logic and MCP cost tracking optimize processing expenses.
- Scalability: The pipeline supports continuous ingestion and expansion of the archive.
- Preservation: Historical accuracy is maintained while making content machine-readable.
This digital transformation unlocks new value from legacy data, supporting scholarship and legal research.
If you have complex, unstructured data that needs to be transformed into actionable knowledge, RILLOO can build a custom AI processing pipeline tailored to your needs. Contact us to explore how we can help you unlock the potential of your archives.